Generative AI has shifted from simple prompt-response wrappers to autonomous Agentic AI workflows capable of function calling, tool execution, and stateful decision making.
What Makes an AI Assistant "Agentic"?
Unlike static chatbots, an Agentic AI Assistant possesses:
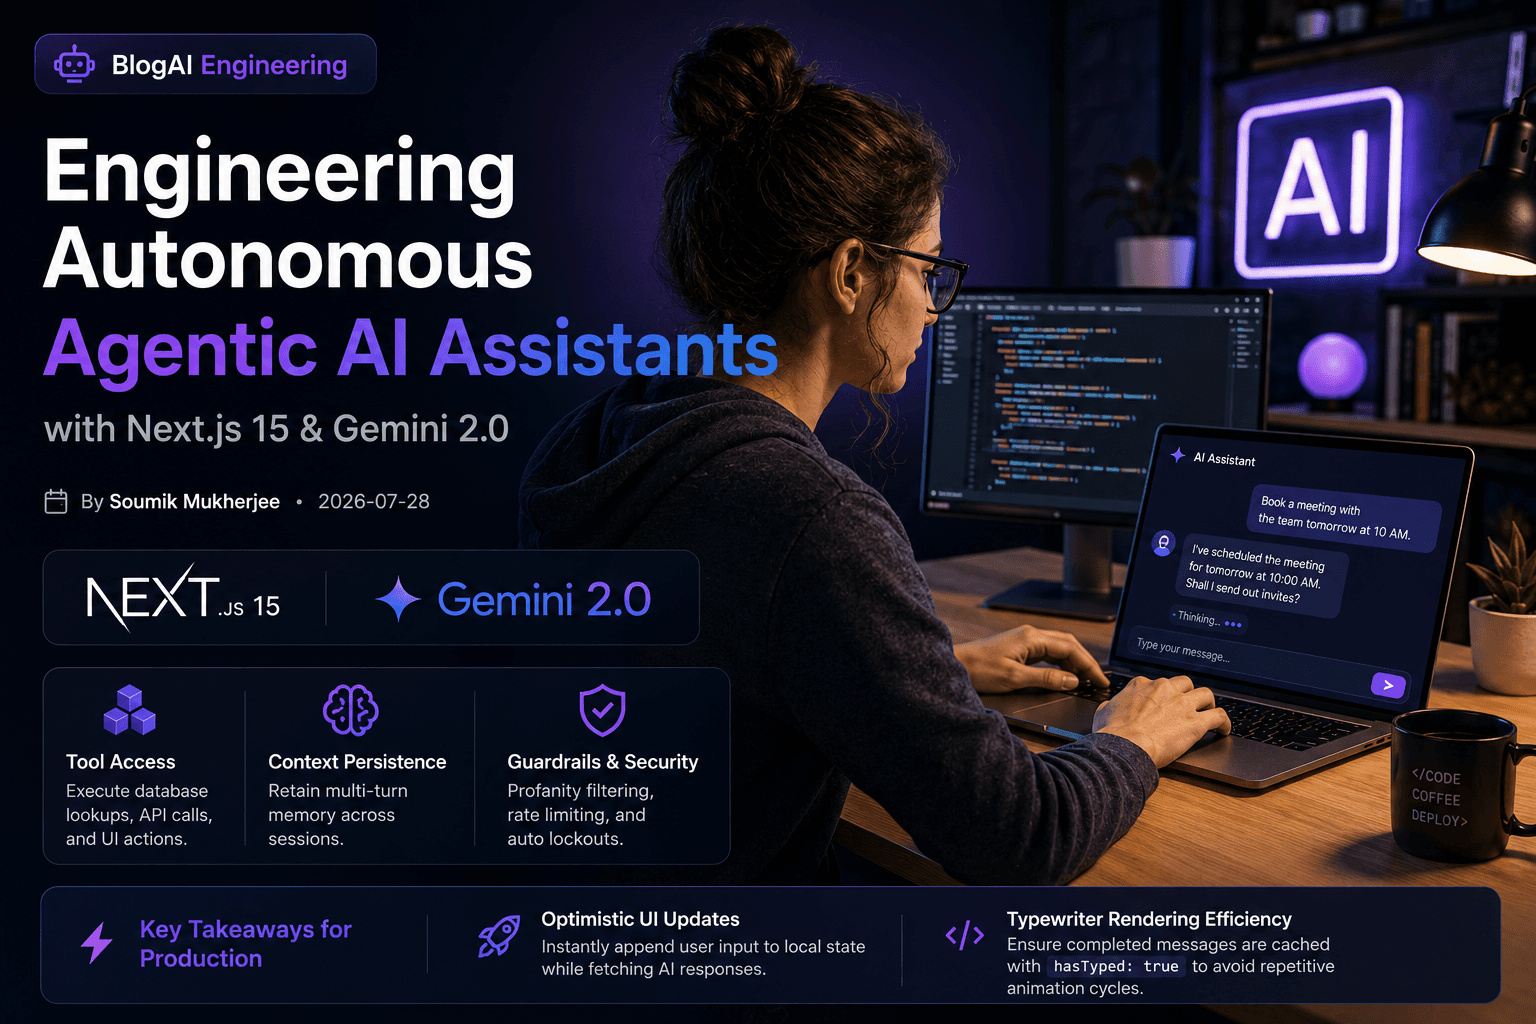
- Tool Access: The ability to execute database lookups, booking actions, external API calls, and local UI state mutations.
- Context Persistence: Retaining multi-turn conversation memory across browser sessions and tab switches.
- Guardrails & Content Auditing: Real-time profanity filtering, rate limiting, and automated security lockouts.
- Autonomous Planning: Decomposing complex user goals into a sequence of discrete, observable actions instead of returning a single canned response.
- Self-Correction: Detecting failed tool calls and retrying with adjusted parameters before surfacing errors to the user.
A genuinely agentic system does not just answer — it acts, verifies, and iterates until the user's goal is satisfied.
Architecture Overview
In Next.js 15 (App Router), we build our AI endpoint using Server-Side Streaming Edge API Routes connected directly to Google Gemini 2.0 Flash models.
export async function POST(request: NextRequest) {
  const { messages } = await request.json();
  // Filter & sanitize multi-turn system prompts
  const response = await fetch(
    "https://generativelanguage.googleapis.com/v1beta/models/gemini-2.0-flash:streamGenerateContent",
    {
      method: "POST",
      headers: { "Content-Type": "application/json" },
      body: JSON.stringify({ system_instruction, contents: messages }),
    }
  );
  return response;
}
The route handler stays thin because streaming, tool dispatch, and memory all live behind small, testable service modules.
Streaming Responses with Gemini 2.0
Streaming is non-negotiable for perceived performance. Instead of buffering a full response, forward the model's token stream to the client:
- Use the streamGenerateContent endpoint and pipe the response body through.
- Emit progress events so the UI can render tokens as they arrive.
- Track a
hasTypedflag per message so completed responses are never re-animated on re-render.
Function Calling & Tool Execution
Agentic behavior depends on exposing real capabilities to the model. Define a typed tool registry:
const tools = {
  searchFlights: { description: "Search available flights", parameters: {} },
  bookAppointment: { description: "Book a calendar slot", parameters: {} },
  lookUpOrder: { description: "Fetch order status", parameters: {} },
};
When the model emits a tool call, your route intercepts it, executes the real function, and returns the result back into the conversation as a tool response. This closes the agentic loop: the model observes real-world output and plans its next step from it.
Context Persistence Across Sessions
Users switch tabs, close browsers, and come back days later. Persist conversation state per user:
- Store normalized message history in a low-latency store (Redis, Postgres, or IndexedDB).
- Scrub sensitive fields before writing to the transcript.
- Sliding-window truncation keeps token budgets predictable without losing the user's goal.
Guardrails & Content Auditing
Production AI needs rails:
- Profanity & toxicity filters running on every inbound and outbound message.
- Prompt-injection defenses that strip hidden instructions before they reach the model.
- Confidence thresholds that force the assistant to ask for clarification instead of hallucinating.
Rate Limiting & Security Lockouts
Protect your spend and your users:
- Per-user sliding window limits (e.g., 40 requests / 15 minutes).
- Exponential backoff after repeated violations.
- Automatic lockout with manual review triggers for suspicious activity patterns.
Optimistic UI & Typewriter Rendering
- Optimistic UI Updates: Instantly append user input to local state while fetching AI responses to eliminate perceived latency.
- Typewriter Rendering Efficiency: Ensure completed messages are cached with
hasTyped: trueto avoid repetitive animation cycles upon component re-renders.
Error Handling & Fallbacks
Every external dependency will fail eventually:
- Retry idempotent tool calls with exponential backoff.
- Fall back to a non-agentic, retrieval-only mode when the model endpoint degrades.
- Surface friendly, actionable errors instead of raw network failures.
Observability & Cost Optimization
Treat the assistant like any production workload:
- Trace every turn: latency, tokens in/out, tool calls, and tool durations.
- Log aggregate spend per model, per user, and per feature.
- Cache identical tool results and reuse them across sessions when safe.
Key Takeaways for Production
- Start with a narrow, well-defined tool surface; expand only as user flows prove out.
- Stream everything — buffering kills the UX.
- Persist context, audit content, and rate-limit aggressively.
- Measure token cost per resolved goal, not per turn.